1.5 · How the stack works
What ioctl(KVM_RUN) Does: The VM Exit Loop Explained
The previous post showed that guest code runs at full speed until it touches a device, and that control then has to reach QEMU. This post looks at how.
ioctl(vcpu_fd, KVM_RUN) is the most important line in the whole stack. libvirt, the XML, the
device models and virtio are all built around this one call, repeated in a loop.
The call makes sense once you know what a file descriptor is and what ioctl does in general, so
this post builds up to it.
File descriptors, briefly
If you know what a file descriptor is, skip this section.
A file descriptor is a small, non-negative number that identifies something a process has open.
The kernel keeps a private table for every running process. When a program opens something, the kernel records it in the next free slot of that table and hands back the slot’s number. From then on, the program refers to it only by that number.
Every process starts with three already open:
| Number | Name | Usually |
|---|---|---|
| 0 | standard input | The keyboard, through the terminal |
| 1 | standard output | The terminal |
| 2 | standard error | The terminal |
The next thing a program opens gets the lowest free number, usually 3. It does not matter whether it is a
file, a network connection, a device or one of KVM’s virtual processors: the kernel handles them all through
file descriptors, with the same calls, such as read(), write() and close(), and works out what to do from
what the number refers to.
Here are a process’s file descriptors on my Raspberry Pi 5, on sbrsl, one of its SD cards:
admin@sbrsl:~ $ ls -l /proc/self/fd
total 0
lrwx------ 1 admin admin 64 Oct 16 18:50 0 -> /dev/pts/0
lrwx------ 1 admin admin 64 Oct 16 18:50 1 -> /dev/pts/0
lrwx------ 1 admin admin 64 Oct 16 18:50 2 -> /dev/pts/0
lr-x------ 1 admin admin 64 Oct 16 18:50 3 -> /proc/1868096/fd
/proc/self always refers to the process looking at it, here ls itself. Its descriptors 0, 1 and 2 all point to
/dev/pts/0, the terminal window: its input, output and errors all go there. Number 3 is the folder ls opened to
read this very list, and it got the lowest free number.
ioctl: for everything read and write cannot express
read() and write() are good at moving bytes, but not at controlling a device.
You cannot write() to a CD drive to make it open its tray. There is no sensible way to read() a serial port’s speed,
or to say “change it to 115,200” as a stream of bytes. These are control operations on a device, not transfers of data.
Unix solves this with ioctl, short for input/output control: a general-purpose call for sending commands to whatever a
file descriptor refers to.
int ioctl(int fd, unsigned long request, ...);| Argument | What it is |
|---|---|
fd | The file descriptor to send the command to |
request | The command, as a number the device’s driver understands |
... | Optionally, a pointer to data the command needs |
The driver behind the file descriptor decides what each command means. That makes ioctl a way for any driver to offer operations
the ordinary file interface never planned for. Terminals use it to change their window size, network code uses it to configure
interfaces, and KVM uses it to run an entire virtual machine.
KVM’s three levels of file descriptor
KVM appears as /dev/kvm, a character device, as post 2.1 showed. QEMU
opens it and gets a file descriptor. That descriptor, and a series of ioctl calls, are the whole interface between QEMU and KVM.
KVM arranges it in three levels, each created from the one above:
| Level | Created by | Represents | Commands it accepts include |
|---|---|---|---|
| The system | open("/dev/kvm") | KVM as a whole | KVM_CREATE_VM |
| A VM | ioctl(KVM_CREATE_VM) | One virtual machine, with its memory and devices | KVM_SET_USER_MEMORY_REGION, KVM_CREATE_VCPU |
| A vCPU | ioctl(KVM_CREATE_VCPU) | One virtual processor | KVM_RUN |
Creating a VM works down those levels:
KVM_CREATE_VM, on the system descriptor, creates an empty VM, and returns a descriptor for it.KVM_SET_USER_MEMORY_REGION, on the VM’s descriptor, gives it memory. QEMU sets aside ordinary memory in its own process, withmmap, and tells KVM to use it as the guest’s physical memory. That is also the boundary of the guest’s world: it can only reach memory registered this way.KVM_CREATE_VCPU, on the VM’s descriptor, creates a virtual processor, and returns a descriptor for it.KVM_RUN, on the virtual processor’s descriptor, means: run this processor now.
What KVM_RUN actually does
KVM_RUN does not behave like an ordinary function call. When a QEMU thread calls ioctl(vcpu_fd, KVM_RUN), the thread enters the guest, and
the call does not return until the guest does something KVM cannot deal with by itself.
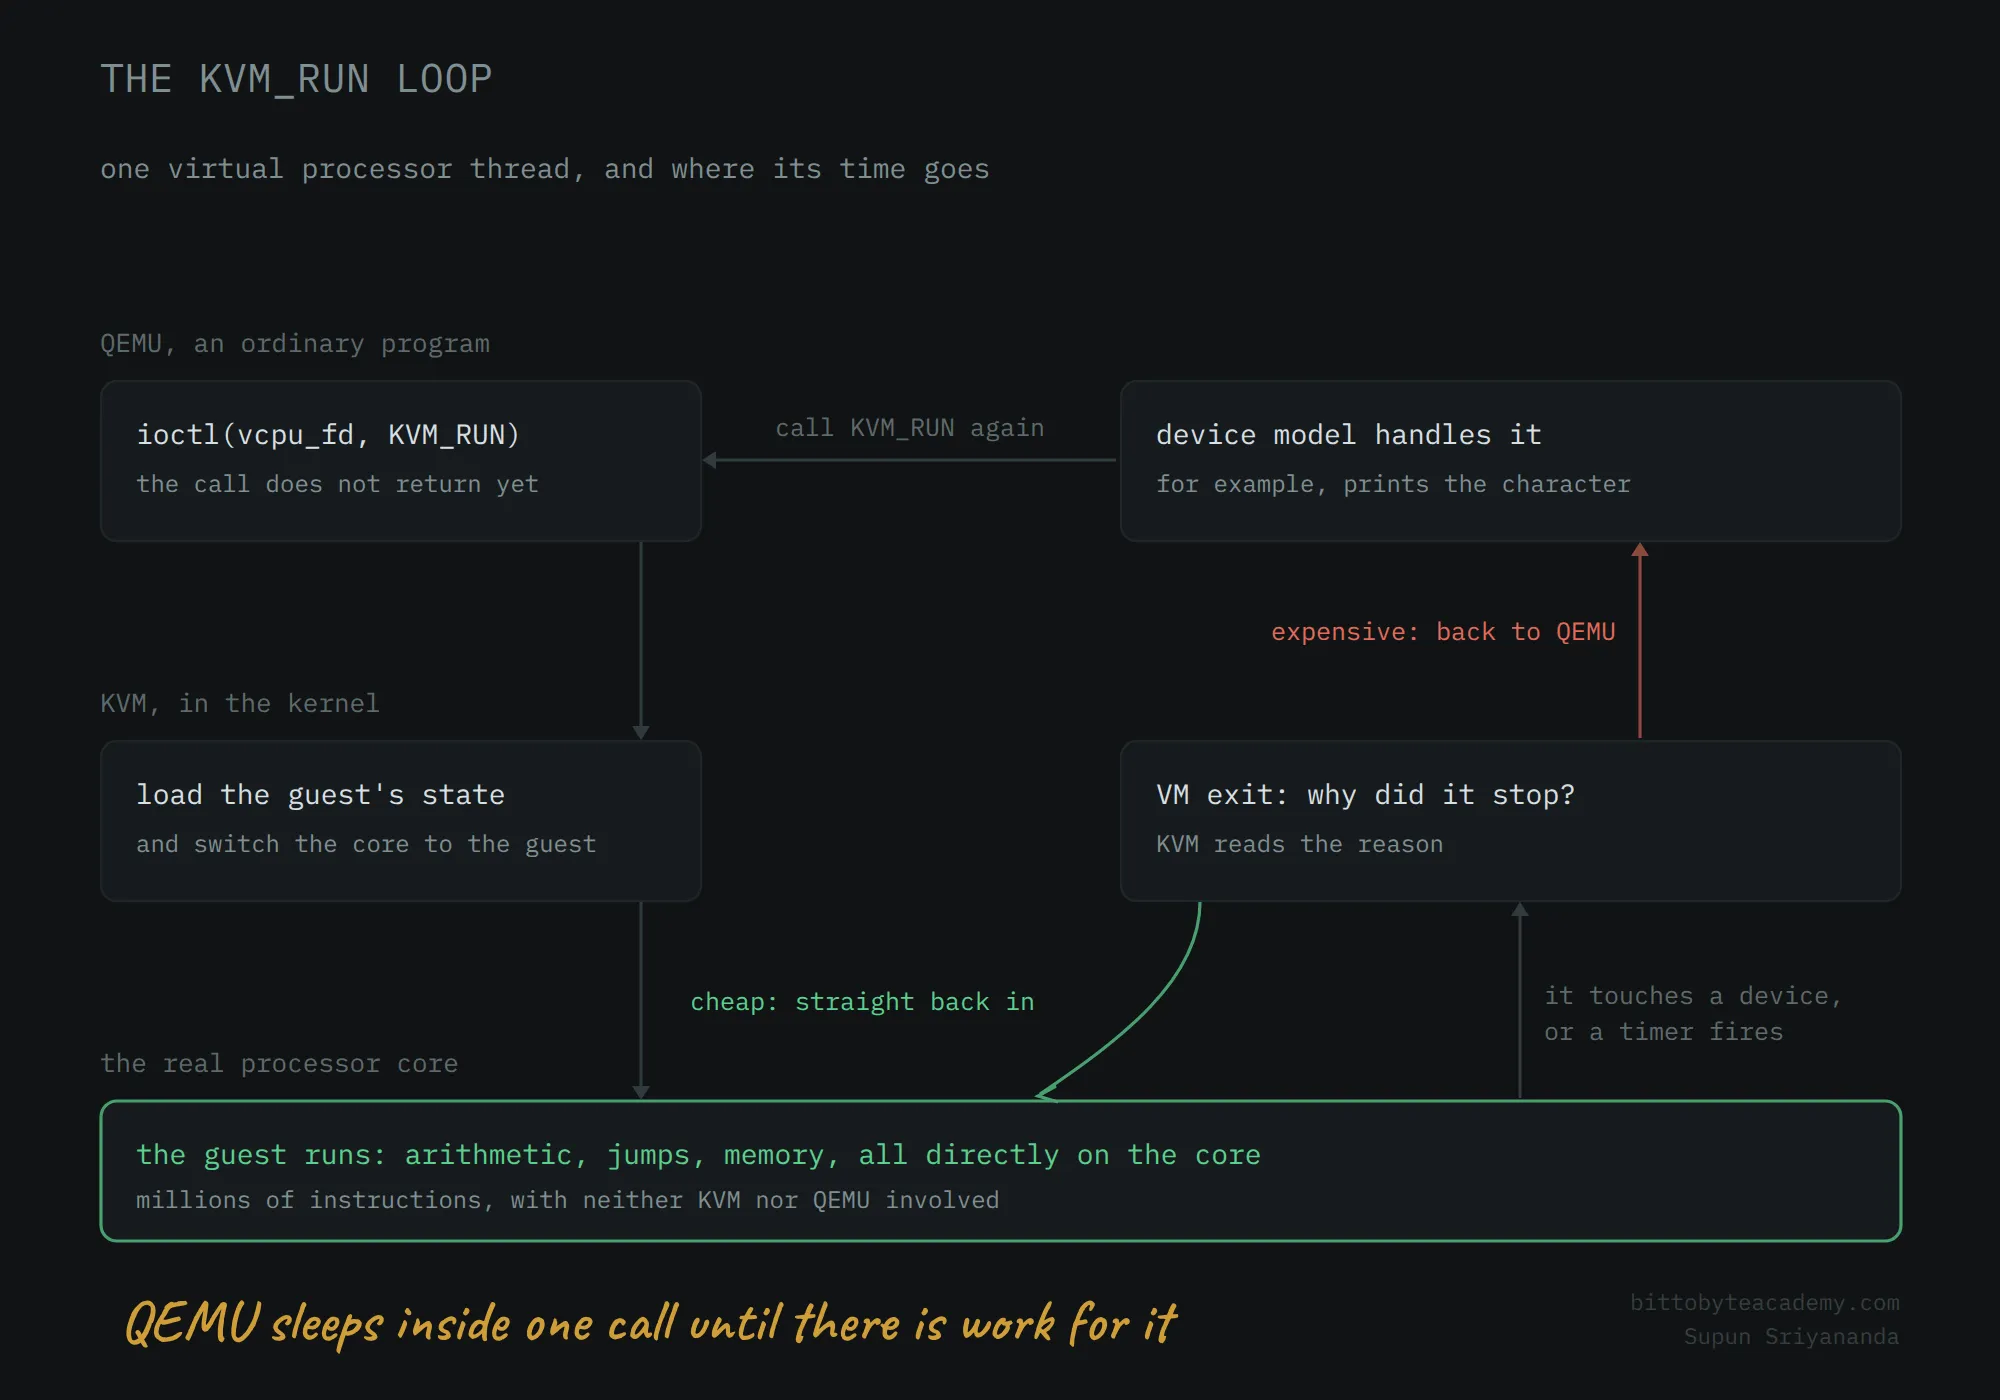
Step by step:
- A QEMU thread calls
KVM_RUN, and passes into the kernel, to KVM. - KVM loads the guest’s saved processor state, its registers and the position in its code, onto the real core, and switches the core to the guest, using the EL2 feature from post 1.2.
- The real core runs the guest’s code directly, at full speed. KVM is not involved instruction by instruction, and from QEMU’s point of view, the call has simply not returned yet.
- Eventually, the guest does something that traps, such as touching a device. That is a VM exit: the processor stops the guest and returns to KVM, which saves the guest’s state and looks at why it stopped.
- If KVM can deal with it itself, it goes straight back into the guest. QEMU never wakes.
- If it cannot, because the guest touched a device only QEMU imitates, the call finally returns to QEMU, with the reason. QEMU’s device model deals
with it, and calls
KVM_RUNagain.
Three things follow from this.
The call blocks, on purpose, for a long time. From QEMU’s point of view, it called a function that did not return for millions of the guest’s instructions. All that time, QEMU’s thread is waiting inside one call. It is not checking or supervising anything: it is asleep, and only wakes when there is work for it.
Crossing into and out of the guest costs time. Entering the guest means loading its registers onto the core, and leaving means saving them again. That is part of why an exit is expensive.
Not every exit reaches QEMU. If the kernel can deal with the cause itself, such as a timer, or the interrupt controller KVM handles in the kernel, KVM goes straight back into the guest, and QEMU never knows there was an exit.
Cheap exits and expensive exits
So there are two kinds of exit:
| Cheap | Expensive | |
|---|---|---|
| Handled by | KVM, in the kernel | QEMU, after the call returns |
| Does QEMU wake? | No | Yes |
| Examples | Timer interrupts, and, on ARM64, the GIC, the interrupt controller, which KVM imitates in the kernel | Any device that only QEMU imitates, such as a serial port |
When people say “VM exits are expensive”, they mean the second kind. Interrupts happen far too often to send each one out to QEMU, which is why KVM handles the interrupt controller in the kernel at all.
That also explains a line from the Pi’s kernel messages, in post 1.2: GICV region size/alignment is unsafe, using trapping. On this board, some of the guest’s
accesses to the interrupt controller have to trap, causing more exits than on other hardware, but cheap ones, handled by KVM without waking QEMU.
How QEMU finds out what happened: the kvm_run structure
When KVM_RUN does return, QEMU needs to know why, and an ioctl’s return value, a single number, is far too little. So KVM uses shared memory.
When a virtual processor is created, KVM gives QEMU a small area of memory that both of them can see, laid out as a struct kvm_run. KVM writes the
details of each exit into it before returning, and QEMU reads them straight away, with no further calls. For the example below, it would hold:
| Field | Value |
|---|---|
exit_reason | KVM_EXIT_MMIO |
mmio.phys_addr | 0x09000000 |
mmio.data | 0x48, the letter H |
mmio.len | 1 byte |
mmio.is_write | 1, a write |
exit_reason says what kind of exit it was. KVM_EXIT_MMIO means the guest accessed a device’s memory region, the mechanism from the previous post, and the
usual case on ARM64. QEMU finds which device model owns that address, calls it, and loops round.
Here is the whole cycle, for the guest writing the letter H to the serial port at 0x09000000:
- The guest runs an ordinary store instruction. It has no idea anything unusual is happening.
- The address is in a device’s region, so the processor traps: a VM exit.
- KVM sees that it is an MMIO access to an address it does not handle itself, fills in
kvm_run, and returns from theioctl. - QEMU wakes, reads
exit_reason, and hands the access to its PL011 serial port model. - The serial port model writes
Hto wherever the console is connected: your terminal. - QEMU calls
ioctl(KVM_RUN)again, and the guest carries on with its next instruction.
Every character a guest prints on its serial console goes round that loop. Watching an installer’s text scroll past in virsh console means watching this cycle
thousands of times.
Why this matters for the rest of the series
Once this round trip is clear, several later topics become easier.
virtio, in post 1.6, is the answer to expensive exits. If each round trip costs time, make each one carry more work. virtio puts many operations behind a single notification, so one exit is shared across dozens of them.
Tying virtual processors to cores. The thread running the KVM_RUN loop is an ordinary thread, so unless told otherwise, the Linux scheduler may move it from
one physical core to another, as it does with any thread. Each move leaves behind the data that core had cached for it. Tying the thread to one core keeps that cache
warm, which helps the guest’s performance, especially with frequent exits.
The monitor and KVM_RUN are different things. It is easy to confuse them. The monitor, QMP, the QEMU Machine Protocol, is a socket that tools such as libvirt use to
control QEMU from outside, as post 3.9 shows in libvirt’s QEMU command. KVM_RUN is the call QEMU makes into the kernel to run
the guest. They are two separate paths.
So, in one sentence: ioctl(vcpu_fd, KVM_RUN) starts the guest, the guest runs directly on the real hardware until something traps, and the call only returns when QEMU
has a device to imitate. That call, repeated in a loop, is what a running virtual machine is.
Summary
- A file descriptor is a number identifying something a process has open, in a table the kernel keeps for each process.
ioctlis the general-purpose call for commands thatreadandwritecannot express.- KVM is controlled entirely through
ioctlon/dev/kvm, in three levels: the system, a VM, and a virtual processor. KVM_RUN, on a virtual processor, enters the guest, and does not return for as long as the guest runs directly: possibly millions of instructions.- Cheap exits are handled inside KVM, such as timers and the interrupt controller, and never wake QEMU. Expensive exits return to QEMU, so its device model can run.
- KVM reports why it stopped in the shared
kvm_runstructure.exit_reasontells QEMU which device model to call. - Every character on a guest’s serial console is one full round trip through this loop.
Comments